In November 2016, I am at Big Data Spain in Madrid for the first time. A great conference with many awesome speakers and sessions about very hot topics such as Apache Hadoop, Spark Spark, Streaming Processing / Streaming Analytics and Machine Learning. If you are interested in big data, then this conference is for you! My two talks:
Here I wanna share the slides and a video recording of the latter one…
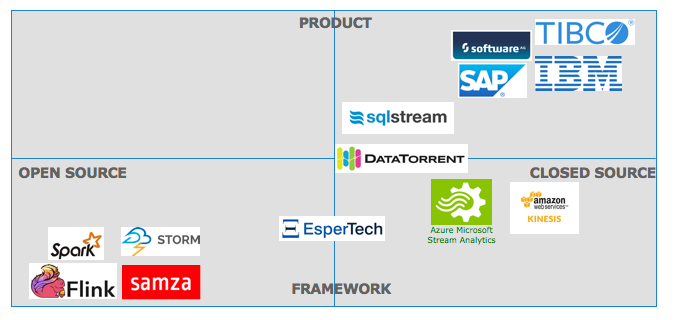
This session discusses the technical concepts of stream processing / streaming analytics and how it is related to big data, mobile, cloud and internet of things. Different use cases such as predictive fault management or fraud detection are used to show and compare alternative frameworks and products for stream processing and streaming analytics.
The focus of the session lies on comparing
The session will also discuss how stream processing is related to Apache Hadoop frameworks (such as MapReduce, Hive, Pig or Impala) and machine learning (such as R, Spark ML or H2O.ai).
The following slide deck is a more extensive version of the talk at Big Data Spain (as the conference talks were only 30 minutes):
The video recording walks you through the above slide deck:
As always, I appreciate any comments, questions or other feedback.
The Industrial IoT Landscape Q4 2026 maps vendors and open source from edge to cloud…
Telecom has more orchestration standards than any other industry, and the maturity stops at the…
Jev by TypeSafe AI returns a calibrated probability instead of text. In a workflow that…
Jev by TypeSafe AI returns typed decisions with calibrated probabilities in a few hundred milliseconds.…
System One models such as Jev by TypeSafe AI answer typed questions with calibrated probabilities…
A working Python cron job moved to Kestra, the open source workflow orchestration platform, without…